Advanced Learning  /  Intermediate Track
Call +91 78925 81597
Intermediate Track  |  Course 3

Data Engineering & Big Data Analytics

ETL pipelines, data warehouses, big data tools and cloud data processing.

  • 3 Months program with intermediate learning
  • Build industry-oriented projects with expert trainers
  • Certificate on completion, internship opportunity and placement guidance
  • Classroom batch at Balmatta, Mangalore, or live online

Send an Enquiry & Get a Brochure

What describes you best *

Send enquiry
Course Duration3 Months
Time Commitment2 Hours/day
EligibilityPursuing college / Graduate
Learning ModeOnline / Offline
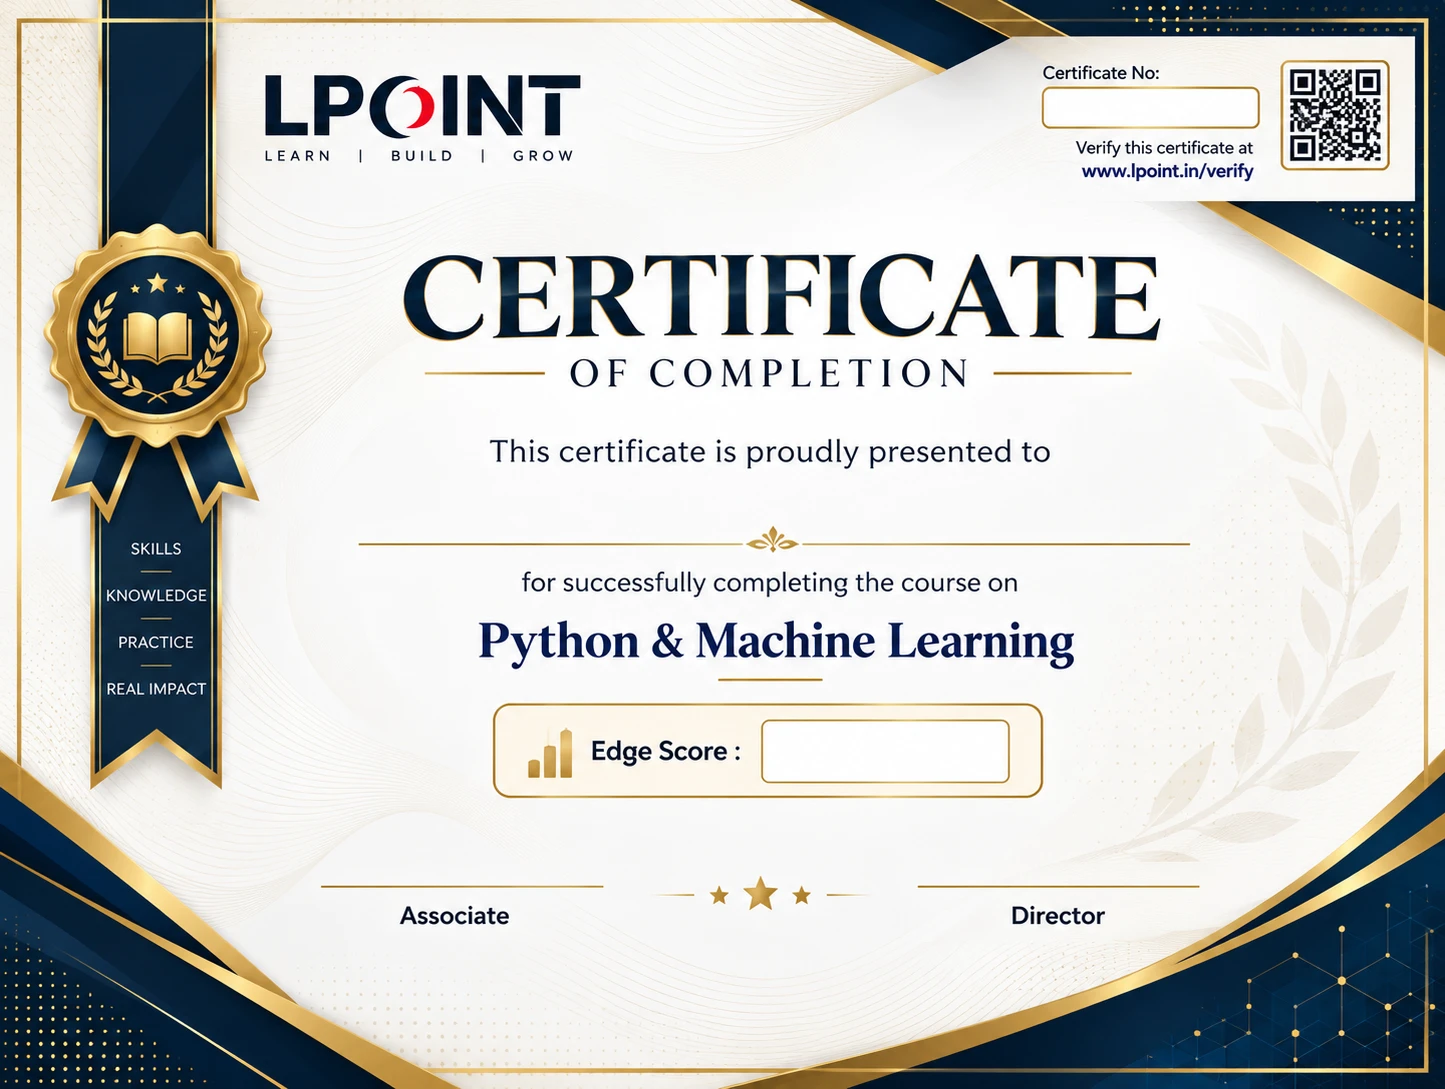
Sample LPOINT certificate of completion with certificate number, QR verification and Edge Score

Why choose this course?

ETL pipelines, data warehouses, big data tools and cloud data processing.

Expert Trainers

Learn from experienced trainers who guide you step by step, from the basics to real projects.

Industry-Oriented Projects

Build hands-on projects based on real-world use cases to apply what you learn and strengthen your portfolio.

Placement Guidance

Get help with resume building, interview preparation and job search so you are ready for the job market.

Internship Opportunity

Get an opportunity to gain practical, hands-on experience through an internship after the course.

Certificate on Completion

Receive a certificate on completing the course to showcase your skills to employers.

Face-to-Face Interview with Industry Experts

Take part in a face-to-face interview with industry experts to get feedback and build confidence for real interviews.

What you will learn

Every dashboard and machine learning model depends on reliable data. In this course you will learn how data engineers collect data from many sources, clean and transform it, store it in warehouses, and process it at scale with big data tools and cloud services. The course ends with real-world data pipeline projects.

Students learning together
01ETL & Data Pipelines
  • Extracting data from files, APIs and databases
  • Cleaning and transforming data
  • Loading data into target systems
  • Data quality checks and error handling
02Data Warehousing & Modelling
  • Data warehouse and data lake concepts
  • Star and snowflake schemas
  • Fact and dimension tables
  • Designing for analytics
03Advanced SQL
  • Joins, subqueries and CTEs
  • Window functions
  • Indexes and query optimisation
  • SQL with Python
04Big Data with Hadoop & Spark
  • Big data and distributed computing basics
  • Hadoop and Hive overview
  • PySpark DataFrames and Spark SQL
  • Batch processing of large datasets
05Workflow Automation
  • Pipeline orchestration with Airflow
  • DAGs, tasks and scheduling
  • Handling failures and retries
  • Monitoring and logging
06Cloud Data Processing
  • Cloud storage and managed data services
  • Building pipelines on the cloud
  • Security and access basics
  • Cost awareness for data workloads

Toolkit

PythonSQLPySparkApache AirflowHadoop / HiveData WarehouseCloud StorageGitHub

Industry-oriented projects

01

Sales Data ETL Pipeline

Extract sales data from files and APIs, clean it with Python and load it into a database.

What you will do

  1. Extract sales data from files and an API
  2. Clean and transform it with Python
  3. Load the clean data into a database
  4. Re-run the pipeline and check the data quality

Skills you will use

PythonETLData cleaningSQL
Project outcome

A working pipeline that takes raw sales data and loads clean data into a database.

02

Retail Data Warehouse

Design a star schema and answer business questions with analytical SQL queries.

What you will do

  1. List the business questions a retail team asks
  2. Design a star schema with fact and dimension tables
  3. Load sample retail data into the warehouse
  4. Answer the questions with advanced analytical SQL

Skills you will use

Star schemaFact and dimension tablesAdvanced SQL
Project outcome

A designed warehouse with analytical queries that answer real business questions.

03

Big Data Log Analysis

Process large log or transaction datasets with PySpark and summarise the results.

What you will do

  1. Load a large log or transaction dataset into Spark
  2. Clean and transform it with PySpark
  3. Run Spark SQL queries across the full data
  4. Summarise the findings clearly

Skills you will use

PySparkSpark SQLBatch processing
Project outcome

A Spark job that processes a large dataset and a clear summary of the results.

04

Capstone: End-to-End Data Pipeline

Capstone

Build and schedule an automated pipeline on the cloud, from raw data to reports, then present your results.

What you will do

  1. Plan the pipeline from raw data to final reports
  2. Build the extract, transform and load steps in Python
  3. Schedule it with Airflow and store data in cloud storage
  4. Test the run, then present the results

Skills you will use

AirflowCloud storagePythonPresentation
Project outcome

An automated, scheduled cloud pipeline from raw data to reports, presented to an audience.

Who Is This Course For?

Start your Data and AI journey with Python, Statistics, SQL and machine learning.

Degree freshers on campus Students learning together Working professional learning data skills Beginner learning at home

Start your Data Engineering career

  • Open to BCA, BSc (CS), BE / BTech, MCA, MSc (CS) and MTech students and graduates
  • Learn how data engineers collect, clean, transform and store data
  • Build pipeline and data warehouse projects for your resume and portfolio
  • Get placement guidance: resume, mock interviews, aptitude and group discussion
What you gain

Real data pipeline projects and a certificate that help you stand out in campus and off-campus interviews.

Ready for the next level

  • Beginner Track students ready for the next level
  • Build on your Python and SQL basics
  • Learn ETL, data warehousing, Apache Spark and Airflow
  • Finish with an end-to-end data pipeline project
What you gain

A smooth step from the basics to building reliable data pipelines.

Move into data engineering roles

  • Working professionals moving into data engineering roles
  • Build ETL pipelines with Python and SQL
  • Process large datasets with Apache Spark and automate workflows with Airflow
  • Online and offline batches with 2 hours of learning per day fit around your job
What you gain

The skills to design, automate and run data pipelines on the cloud.

Work with big data

  • Developers and database professionals who want to work with big data
  • Prerequisites: SQL basics (SELECT, WHERE, JOIN, GROUP BY) and Python basics; basic Pandas is helpful
  • Learn Hadoop, Hive, PySpark and Spark SQL for large datasets
  • New to Python? Start with Course 1: Python for Data Science & Machine Learning
What you gain

The ability to take your database experience to big data tools and cloud data processing.

Placement guidance

Prepare to take your skills into the job market through:

Resume GuidanceProject PresentationTechnical Interview PreparationMock InterviewsAptitudeHR RoundTechnical RoundGroup DiscussionLinkedIn GuidanceJob Search Guidance

Frequently asked questions

What should I know before joining?

Knowing Python basics is a plus (variables, loops, functions and data types), along with SQL basics such as SELECT, WHERE, JOIN and GROUP BY. Basic Pandas is helpful. If you are new to Python, start with Course 1: Python for Data Science & Machine Learning.

Who can join this course?

Degree freshers (BCA, BSc CS, BE/BTech, MCA, MSc CS, MTech), Beginner Track students ready for the next level, working professionals moving into data engineering roles, and developers and database professionals who want to work with big data.

How long is the course?

Three months, planned as a 12-week roadmap from ETL and SQL foundations to cloud pipelines and a capstone project.

Which tools will I learn?

Python, SQL, PySpark, Apache Airflow, Hadoop and Hive, data warehousing and cloud storage, with GitHub for your project work.

Will I get a certificate?

Yes. You receive a certificate on completion, and an internship opportunity is part of the program.
Contact Us

Visit us at 6th Level, Oberle Towers, Balmatta, Opp. Juice Junction, Mangalore, Karnataka 575001 · +91 78925 81597 · (0824) 4256456

WhatsApp us

For any queries, you can WhatsApp us at +91 78925 81597

Mail us

For any queries, you can mail us at contact@lpoint.in